I have run pgvector in production for over two years, first on a document search tool with about 600K embeddings and currently on a customer support assistant holding just over 4 million vectors at 1,536 dimensions. It works. It also has sharp edges that the posts praising it tend to skip past.
The pitch is simple: you already run PostgreSQL, so why add a second database just for embeddings. For many small and mid-size workloads, that pitch holds up. But “it works” and “it works at your recall and latency targets” are different claims, and closing that gap takes real tuning. This post covers what I learned the hard way: the two index types and when each fits, how to measure and tune recall without guessing, the operational failure modes nobody warns you about, and the honest point where a dedicated vector database starts to make sense.
Why pgvector Earns Its Place
pgvector is an open-source PostgreSQL extension maintained by Andrew Kane and contributors, with the current release line at 0.8.x as of mid-2026 and full HNSW support since version 0.5.0 shipped in July 2023. Once installed, it gives you a vector column type, distance operators for L2, inner product, and cosine distance, and approximate nearest neighbor (ANN) indexes. Everything is plain SQL. Your embeddings live in the same database as your users, your documents, and your permissions logic. No sync pipelines, no eventual consistency between your vector store and your source of truth, no second system to back up.
That last point is underrated. With Pinecone or Weaviate sitting next to Postgres, every delete or update has to propagate. I have debugged exactly one consistency incident since moving to pgvector, and it was my own bug, not a sync lag window.
The extension is also free. Dedicated vector databases are not cheap. Pinecone’s pricing starts around $50 per month for a serverless footprint but climbs quickly with vector counts and query volume. On a $40 per month managed Postgres instance you can hold millions of vectors comfortably. If you already know Postgres, the cost comparison is not close at small scale.
The Two Index Types: IVFFlat vs HNSW
pgvector offers two ANN index types. Picking the wrong one is the single most common pgvector mistake I see in the wild.
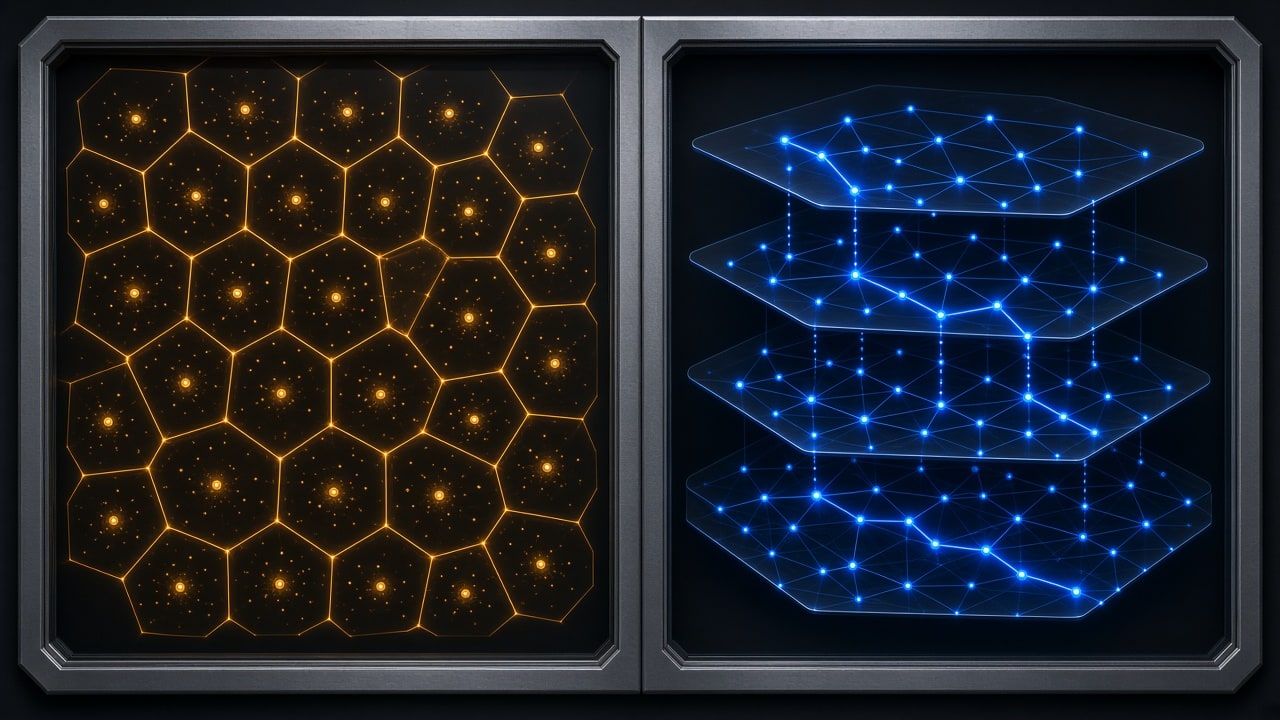
IVFFlat divides your vectors into lists clusters using k-means at build time. At query time it probes the probes nearest clusters and scans only those. It is fast to build and small on disk, but recall drops as your data grows, because the k-means boundaries get stale relative to newly inserted vectors. Anything inserted after the index build may land in a cluster the query never probes.
HNSW (Hierarchical Navigable Small World) builds a multi-layer graph where each vector connects to its neighbors, and search greedily walks the graph toward the query vector. It is slower to build and uses more memory, but delivers much better recall, and recall stays stable as data grows because inserts update the graph incrementally.
Here is the comparison I hand to teams:
| Property | IVFFlat | HNSW |
|---|---|---|
| Build time | Fast (minutes) | Slow (can be hours at 10M+ vectors) |
| Build requires training data | Yes (index scans table at build) | No |
| Recall stability as data grows | Degrades without rebuilds | Stays stable, inserts update graph |
| Disk and RAM footprint | Small | 2-3x larger due to graph layers |
| Recall ceiling | Moderate (0.85-0.95 typical) | High (0.95-0.99 typical) |
| Insert behavior | Fast, index unaffected until rebuild | Slower inserts (graph maintenance) |
For anything resembling a production workload in 2026, use HNSW. IVFFlat made sense before pgvector 0.5.0 when HNSW did not exist. Today its only real niche is huge, relatively static datasets where build time and memory matter more than top-tier recall. I still run one IVFFlat index on a 12-million-vector archive table that gets queried a handful of times a day, and there the fast build genuinely wins. Everything interactive runs HNSW.
Creating one is straightforward:
CREATE INDEX ON documents USING hnsw (embedding vector_cosine_ops)
  WITH (m = 16, ef_construction = 64);
Measuring Recall: The Number You Actually Ship Against
Recall is the fraction of the true top-k nearest neighbors your index actually returns. If the true 10 nearest documents are A through J and your index returns 8 of them, recall@10 is 0.8. pgvector lets you measure this honestly: run a brute-force ORDER BY embedding <=> query LIMIT 10 (which bypasses the index) as ground truth, then compare against the indexed query result.
The tunable that controls recall at query time is hnsw.ef_search. It defaults to 40, which is conservative. Raising it widens the graph traversal and returns better neighbors at the cost of latency. On my 4-million-vector table, moving ef_search from 40 to 100 took recall@10 from 0.91 to 0.97 while p95 latency went from 28ms to 61ms on a db.r6g.xlarge-class instance. The right number is the smallest one that hits your recall target, so measure instead of guessing:
| ef_search | recall@10 (my workload) | p95 latency |
|---|---|---|
| 40 | 0.91 | 28ms |
| 64 | 0.94 | 39ms |
| 100 | 0.97 | 61ms |
| 200 | 0.985 | 118ms |
Two more knobs matter at build time. m (default 16) controls how many connections each node keeps: higher m means better recall, slower builds, and more memory. I use 16 for most workloads and 24 when recall is worth the extra RAM. ef_construction (default 64) controls build quality; raise it if you can tolerate a longer build for a better graph.
One under-documented fact: recall depends heavily on your data distribution. Highly clustered embeddings, like short repetitive support tickets, produce harder graphs than diverse document embeddings. Measure recall on your data, not on repo benchmarks.
The Filtering Trap: Why Half of Your Queries Will Be Slow
This is the section I wish someone had written before my first pgvector deployment. ANN indexes work great on pure vector queries. The moment you add WHERE team_id = 42 AND deleted_at IS NULL, performance can fall off a cliff.
The reason is how Postgres plans the query. With default planner settings, Postgres may apply your filters after the index scan, pulling 40 candidate rows from the HNSW index and discarding 35 of them because they fail the filter. If you need 10 results, you get 2. So Postgres scans deeper and deeper, and your 30ms query becomes a 900ms query.
pgvector 0.5.0 added iterative index scans to fix exactly this. With iterative scan enabled, the index yields candidates one at a time and Postgres applies filters per-row, stopping as soon as it has enough matches. Turn it on with SET hnsw.iterative_scan = relaxed_order; at the session or role level.
The catch: the stricter strict_order mode only returns rows in true distance order, which disables some of Postgres’s own plan choices. I recommend relaxed_order for most filtered queries, which preserves most of the speedup while letting Postgres reorder. On my support-assistant workload, a filtered query (WHERE account_id = X AND status = 'active') went from 1.1 seconds to 41ms after switching to iterative scan with relaxed_order. That one setting beat every other tuning change I made combined.
A second pattern helps even more: partial indexes. If 80 percent of your queries filter on status = 'active', build the index only on active rows with CREATE INDEX ... USING hnsw (embedding vector_cosine_ops) WHERE status = 'active'. Partial HNSW indexes cost nothing extra to maintain beyond the inserted rows, and they shrink the search space your queries fight through.
Operational Failure Modes Nobody Mentions
Build time on big tables. Building an HNSW index on 10 million vectors takes hours. Use CREATE INDEX CONCURRENTLY on production, expect it to take even longer, and verify recall on a sample before deploying right after it finishes.
The 2,000-dimension limit. pgvector’s HNSW indexes cap out at 2,000 dimensions per column. OpenAI’s text-embedding-3-large defaults to 3,072 dimensions. You can reduce it to 1,536 via the dimensions parameter, or index a truncated version of the full vector. Know the limit before you design around a model that blows past it.
Memory pressure. HNSW lives in memory for fast traversal. If your index is 8GB and your buffer budget is tight, you get disk reads on every query and your latency numbers look random. Size your instance so the working set fits comfortably in RAM.
Vacuum and bloat. Deleted vectors stay in the index until vacuum processes them, and heavy churn leads to bloat that degrades recall silently. Watch pg_stat_user_tables.n_dead_tup and make sure autovacuum keeps up.
Backups get big. Your embeddings become part of your Postgres backups. Four million vectors at 1,536 dimensions is roughly 25GB of raw float data. Factor that into your backup window and storage costs.
What Most Guides Get Wrong
Most pgvector content falls into two camps, and both are wrong in instructive ways.
The first camp says “just add pgvector and you have vector search,” showing a 20-row demo table and calling it done. At 1,000 rows, everything looks fast. I have watched this pattern lead a team to ship with default ef_search = 40, no recall measurement, and no filtering strategy, then get paged because their “fast” queries took 3 seconds on real data. Vector search is a database problem, not a demo problem, and it needs the same rigor as any indexing decision.
The second camp says dedicated vector databases exist because Postgres “does not scale,” citing benchmarks from datasets with 100 million vectors. That was a fair argument in 2022. With HNSW, iterative scans, and half a decade of maturation, pgvector handles tens of millions of vectors at low-hundreds-of-milliseconds latency in real deployments. The ANN-Benchmarks project and the pgvector repo’s tracked results show HNSW competitive with dedicated engines at moderate scales. For most business workloads, “does not scale” is a claim about a scale you will never reach.
The truth sits in the middle: pgvector is a genuinely strong default, and it still demands the engineering work of any production index. Skip the work and it will hurt you exactly as much as skipping the work on any other database would.
When a Dedicated Vector Database Actually Wins
I am not a pgvector absolutist. There is a real line, and you should know where yours is before you are forced to find it.
A dedicated engine like Pinecone, Weaviate, or Qdrant starts to win when several of these are true:
- You are past roughly 50 to 100 million vectors and still growing. At that scale, index build times, memory requirements, and query latency on Postgres get painful.
- You need single-digit-millisecond p99 at high QPS. Vector DBs shard and replicate specifically for this. Postgres can get close with heroic tuning; dedicated engines get there by default.
- Your embedding workload would starve your transactional database. If vector queries at peak would contend with your checkout flow for the same buffer pool and CPU, separation stops being optional.
- You want managed scaling without a database engineer. A small team that never wants to think about index builds, vacuum tuning, or instance sizing will rationally pay a premium for it to be someone else’s problem.
My decision rule: start with pgvector, keep embeddings colocated with your data until you hit a measured wall, and only then evaluate a dedicated engine. Migrating later means re-embedding and re-indexing, annoying but survivable. Prematurely splitting your data across two systems costs you consistency guarantees forever. Colocation also matches the principle of consolidating infrastructure rather than spreading across a dozen services, which I covered in a past architecture write-up.
The retrieval quality side matters just as much as the infrastructure side. If you are building RAG on top of your vector search, the retrieval patterns make or break those systems, as covered in this RAG knowledge base write-up. Getting cited correctly in AI-driven search depends on related fundamentals from this breakdown of answer-engine visibility. The index is the foundation, but the surrounding pipeline decides whether users trust the answers.
My Production Checklist
If I were setting up pgvector from scratch today, here is the order of operations I follow:
- Install pgvector 0.8.x or later and verify with
SELECT extversion FROM pg_extension WHERE extname = 'vector'; - Generate embeddings with a model capped at 1,536 dimensions or lower (my default is
text-embedding-3-smallat $0.02 per 1M tokens for ingestion, per OpenAI’s pricing page). - Create an HNSW index with
m = 16,ef_construction = 64. - Set
hnsw.ef_search = 100, then measure recall@10 against brute-force ground truth on 200 sampled queries. - Tune
ef_searchdown to the smallest value meeting your recall target, usually between 60 and 150. - Enable
hnsw.iterative_scan = relaxed_orderif any query has filters beyond a tenant ID. - Build partial indexes for your hottest filter combinations.
- Load-test with production-shaped data, not synthetic 20-row demos.
- Monitor dead tuples, index size, and p95/p99 latency.
- Document your recall and latency targets so the next engineer knows what “working” means.
Conclusion
pgvector is not a toy, and it is not a trap. It is a production-grade vector search engine inside the database you already trust, and for workloads up to tens of millions of vectors it is where I start every project. The two decisions that determine whether it serves you well are using HNSW rather than IVFFlat for interactive queries, and treating recall as a measured, tunable target rather than a hope. Add iterative scans for filtered queries and honest monitoring, and you have a system that outperforms most dedicated deployments at a fraction of the cost.
The dedicated vector database conversation is real, but it belongs at a scale most businesses will never reach. Build on Postgres, measure what matters, and let your traffic data rather than vendor marketing tell you when it is time to split.